01
Rendering API
Execute JavaScript and return the final HTML and HTTP status. Ideal for SPAs and dynamic sites.
ScrapingDuck web scraping API handles headless browsers at scale. Render JavaScript, rotate proxies, handle custom browser flows, and stream results in seconds.
curl --get \
  "https://api.scrapingduck.com/v1/scrape/source" \
  --data-urlencode "url=https://example.com" \
--data-urlencode "apiKey=$SCRAPINGDUCK_API_KEY"<!doctype html>
<html lang="en">
<head>
<title>Example Domain</title>
</head>
<body>
<h1>Example Domain</h1>
</body>
</html>Our Services
One endpoint to render pages accurately and return the final HTML – consistent, fast, and reliable.
Execute JavaScript and return the final HTML and HTTP status. Ideal for SPAs and dynamic sites.
Controls that matter. Set user agents, headers, cookies, timeouts, and wait-for-selector to get the DOM you need.
Operational simplicity. Clear status codes, timing metrics, and usage reporting. Webhooks and scheduling are planned additions.
Anti-bot friendly options. Tweak delays and resource loading to reduce friction on sensitive targets. Country targeting and proxy options planned.
Our Scraping API Pricing Plans
Choose a web scraping plan that fits your scale, from small projects to large-scale data extraction. All plans include our full feature set.
FAQ
Here are answers to common questions about how our scraping API works and how it can improve your data extraction process.
Our Features
Our scraping API provides a complete toolkit to handle the most complex web scraping challenges, allowing your business to focus on analyzing the data, not acquiring it.
Effortlessly perform data scraping on modern, dynamic websites that use JavaScript, React, or Vue. Our scraping API renders pages in a real headless browser, ensuring your data extraction captures all client-side content accurately.
Our scraping API solves the problem of IP blocks. All web scraping requests are automatically routed through our vast pool of premium residential and datacenter proxies, ensuring your data scraping tasks run successfully without interruption.
Scraping dynamic websites often requires user interaction. Our API lets you control the browser to click, scroll, and type, ensuring successful data extraction from even the most complex pages.
Whether you need data scraping for one page or millions, our infrastructure is built for performance. This powerful scraping API handles massive concurrency, allowing you to scale your web scraping projects on demand.
Our Mission
Our mission is to make powerful web scraping simple and accessible for everyone. We believe valuable web data should be within reach, not locked behind technical barriers. Our data scraping API handles the complex infrastructure of browsers, proxies, and blocks, so you can focus on what truly matters: using clean, reliable data to power your business.
99%
Reliability
99%
Performance
99.9%
Availability
Use Cases
You bring the parser. We deliver stable, rendered HTML you can trust.
Fetch accurate pricing from JS-heavy sites across regions.
Collect directory and map results and parse downstream.
Monitor newsroom and blog pages as users see them.
Ingest listings and details reliably, then parse on your side.
Testimonials
Trusted by teams that depend on consistent, rendered HTML.
200+ Companies
trust ScrapingDuck
“We swapped our brittle browser farm for ScrapingDuck and our success rate jumped overnight.”
“Setup took minutes. The render controls gave us the DOM our parser expects.”
Contact
Tell us what you need, and our team will help you find the perfect solution for your data collection goals.
Get in TouchBlog
Stay updated with our latest articles. We share practical tutorials, industry insights, and expert tips on web scraping, data engineering, and automation.
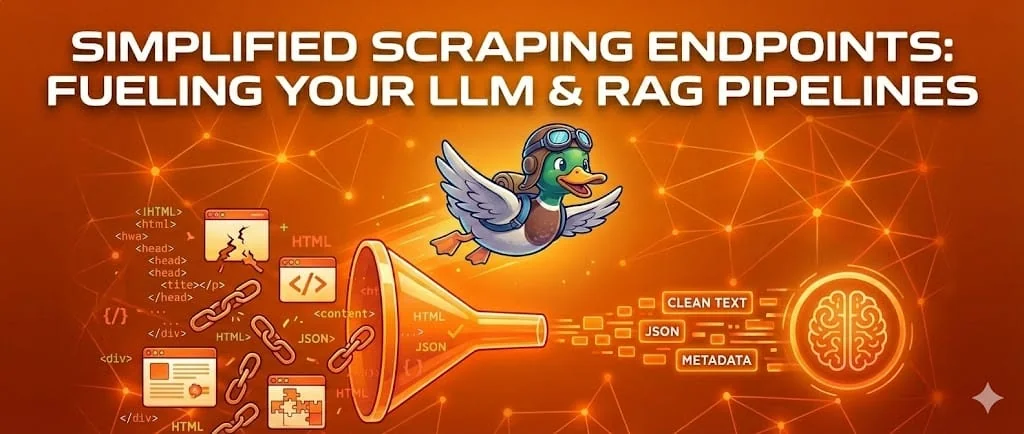
Feed your RAG pipeline with clean web data through ScrapingDuck's simplified endpoints for raw HTML, full results, and article extraction.
Continue Reading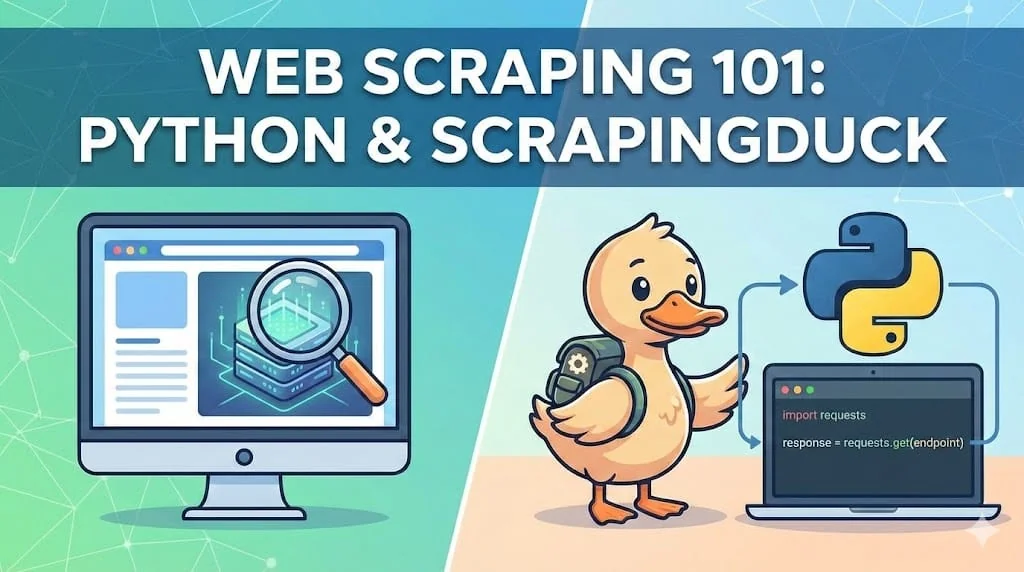
Build your first Python web scraper with ScrapingDuck: fetch rendered HTML, understand the API parameters, and avoid common blockers.
Continue Reading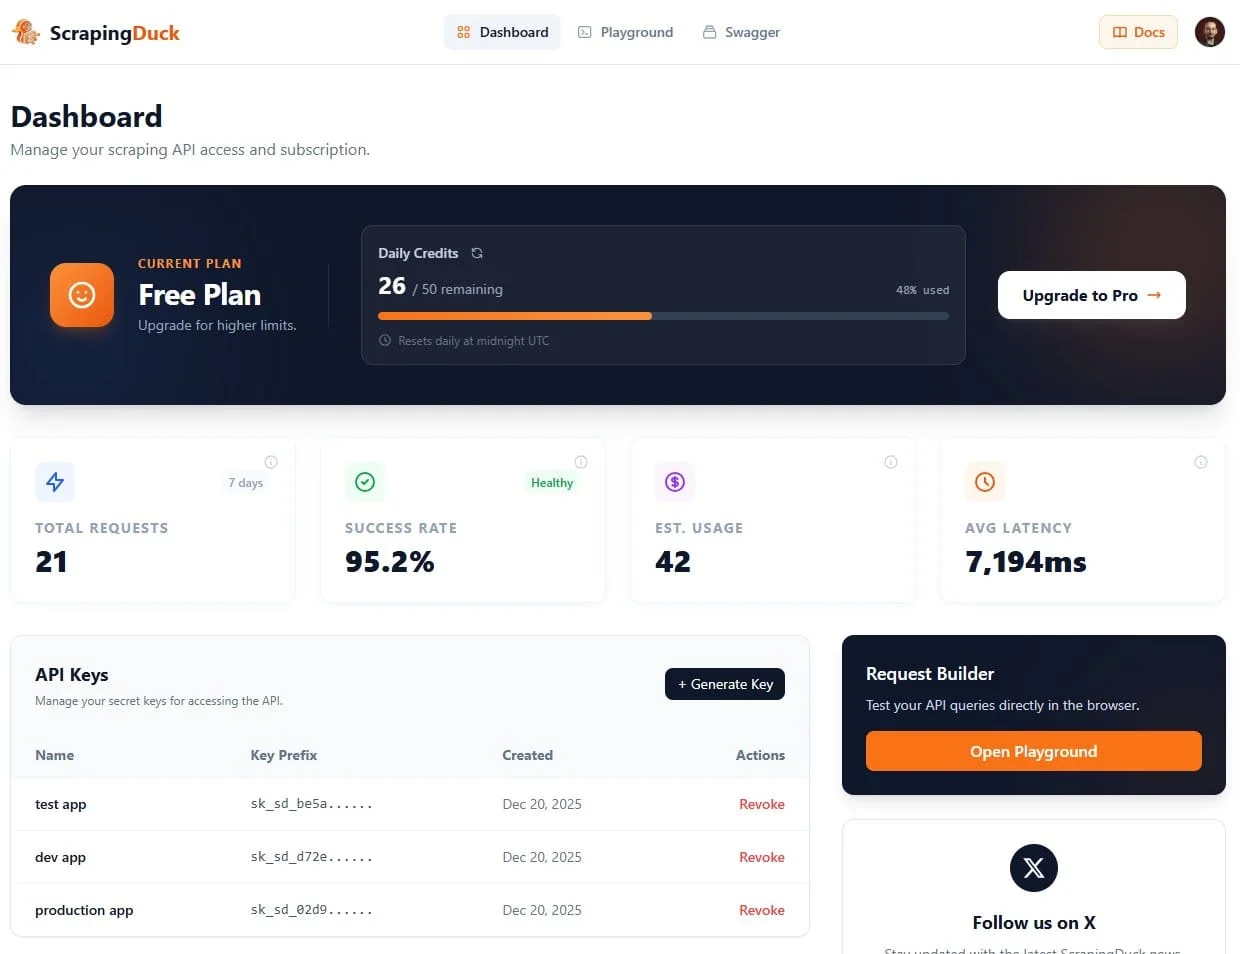
The ScrapingDuck Dashboard brings a request builder, real-time analytics, API key management, and documentation into one place.
Continue Reading